
Manage deployed models
Before you start
Open Models with Operator or Administrator access. Check whether applications or mesh consumers are using a model before interrupting it. Catalog-only models without a Magic Stick activation can be read-only.
When creating a local or external model, use a unique name of 1–63 lowercase letters, numbers or hyphens, starting and ending with a letter or number. The form explains invalid or duplicate names before you submit. An existing model's name cannot be changed in Edit.
| Action | What happens |
|---|---|
| Edit | Opens the saved configuration. Review and save supported changes; runtime-affecting changes can reload the model. |
| Stop | Retains the model definition but disables it. Local runtime resources are removed and routes withdrawn. |
| Start | Recreates the runtime from its saved settings and republishes the route only when ready. |
| Restart | Where offered, restarts the existing engine runtime without creating a second model definition. |
| Logs | Shows bounded logs from the selected activation's local Pods/containers, including startup failures. |
| Remove | Deletes the model activation and its managed runtime. This is not the same as clearing downloaded caches. |
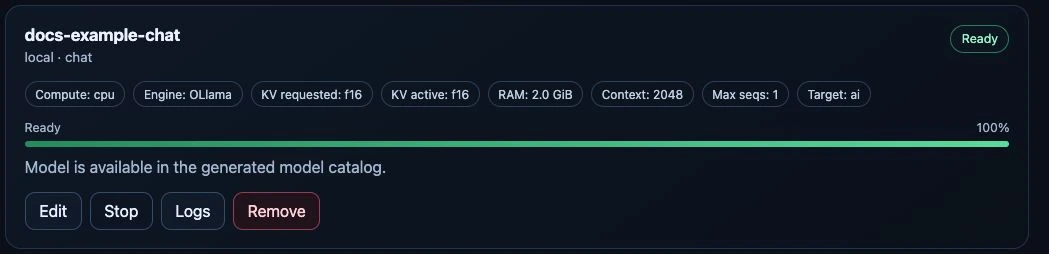
Live test-appliance capture, 24 September 2026. This small, owner-authorized test model illustrates the controls; its parameters are not sizing recommendations.
The common Start/Stop workflow covers Ollama, vLLM, Realtime and external activations. For external models it changes local routing only. Restart controls depend on the engine; Stop followed by Start is the common reload workflow when no separate Restart action is offered.
Understand the lifecycle
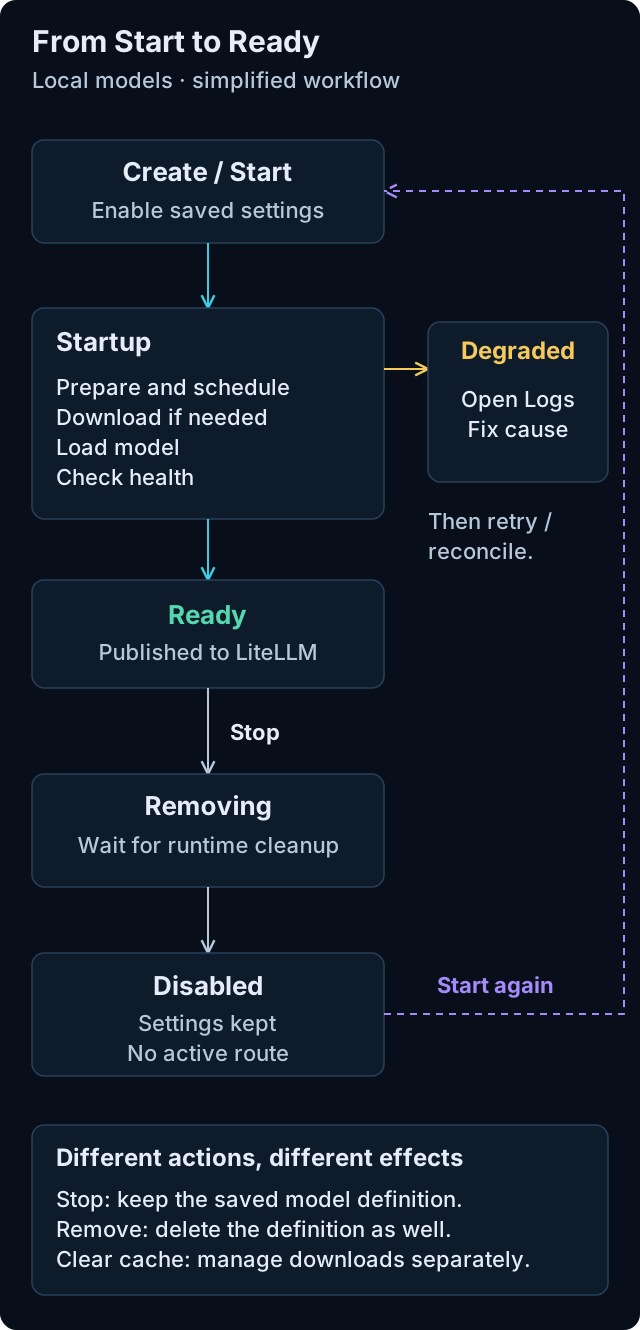
A simplified local-model workflow, not an exhaustive state machine. Open the diagram for full-size labels.
Startup includes dependency preparation, scheduling, any necessary downloads, model loading and health checks. Exact progress labels vary by engine. A failure can report Degraded during startup or after a model was ready: use Logs and the status message to identify the cause before retrying. Some temporary conditions recover through automatic reconciliation.
Stop retains the saved settings. Resources are released only after the runtime and its allocations have terminated. Remove also deletes the model definition; neither action is a substitute for cache cleanup. For external models, Start and Stop control local routing, not the remote provider.
Stop and start again
Choose Stop on the model card and wait for Disabled. The button then changes to Start. Starting uses the saved configuration; you do not need to find the checkpoint or enter its parameters again.
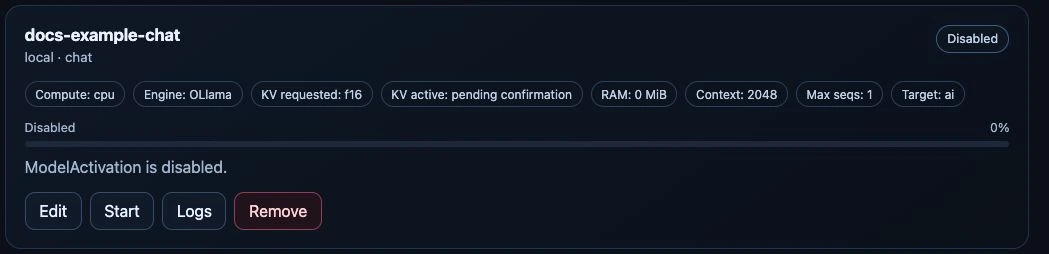
The same test model after Stop, 24 September 2026. The displayed RAM reservation has been released; the model definition and its configured budget are retained.
Edit runtime parameters
Choose Edit, adjust the supported fields, and review the memory budget before selecting Save changes. The model source, engine and hardware target remain unchanged in this dialog. Saving runtime-affecting settings can restart the model.
Create and Edit share the local configuration form for Ollama, vLLM and Omni. The runtime and memory sections show that engine's settings. Advanced starts collapsed and includes CPU reservation/limit for all three; use Use automatic CPU settings to remove an override. Unchanged or reverted settings disable Save, and background status refreshes preserve your draft. Omni retains its profile, custom model source and stage settings when you edit another field.
With NVIDIA DRA, choose physical GPUs from one checkbox list. For a model split across cards, the calculator and its Breakdown both show group totals; host RAM and the model download remain separate. Replicated model copies retain a full per-copy budget. See GPU sharing for the difference between splitting and replicating a model.
GPU models also show System RAM separately from VRAM. Compare While serving, At startup · estimated range and Conservative recommended budget; startup includes transfer buffers and a reclaimable file-cache envelope. For multi-GPU/offloading models, Use recommended RAM allocation changes only the host budget. Existing or manually entered values survive recalculation. A single-GPU model without offloading keeps its current resource profile and displays the RAM recommendation as advisory.
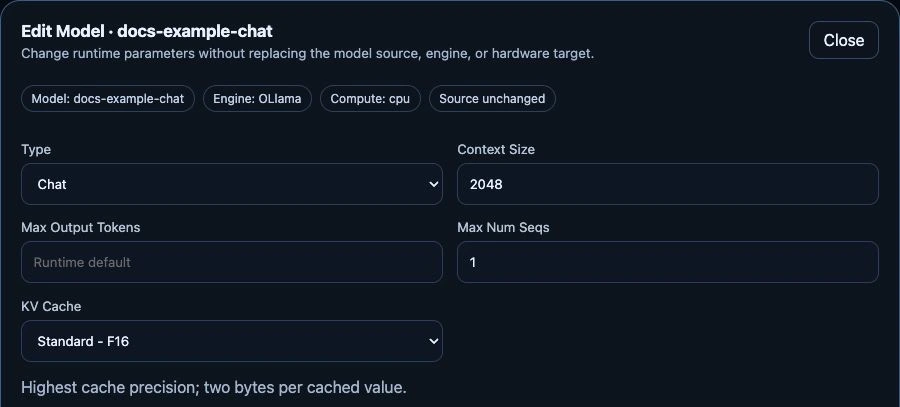
Unchanged editing form for the stopped test model, 24 September 2026. This crop shows the main parameters; memory controls and the save action continue below. No edits were saved for this capture.
Check the result
Stop passes through removal while Pods and GPU allocations terminate. Memory and slots may not become free immediately. Start can download weights again, especially when replacing runtime Pods. Ready means routable; test an inference request before returning the model to users.
If another administrator changed the model while you were editing, refresh the configuration instead of overwriting a stale revision. Changing engine-specific settings must not silently carry incompatible fields to another engine.
For failures, read model diagnostics. For disk cleanup, use model cache management, not manual deletion of running Pods or files.